Menu
Your Cart
Launch week: flagship open-model GPU-hour packs up to 15% off. Keys are delivered instantly, with no shipping. View packs →

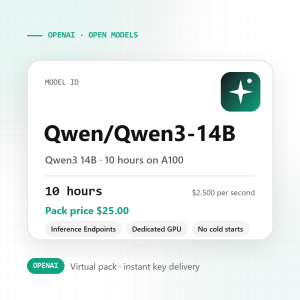
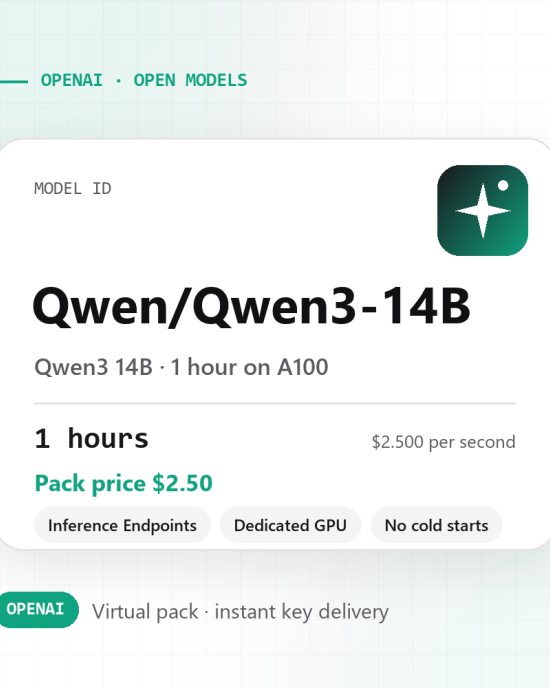
Qwen3 14B · 1 hour on A100

Qwen3 14B · 1 hour on A100
New
Qwen3 14B · 1 hour on A100

Qwen3 14B · 1 hour on A100 - a prepaid inference-hour pack for Qwen/Qwen3-14B, billed at Hugging Face's published Inference Endpoints rate of $2.50 per hour on A100 80GB.

What you get

  • 1 hour(s) of dedicated A100 80GB inference.
  • The model loaded from the Hub: Qwen/Qwen3-14B.
  • No shipping: the endpoint key is issued once the order completes.

Quick start

curl -X POST "$ENDPOINT_URL/v1/chat/completions" \
  -H "Authorization: Bearer $HF_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{"model": "Qwen/Qwen3-14B", "messages": [{"role": "user", "content": "Hello"}]}'
Model Specs
Model ID kimi-k1.5
Context Window 128K tokens
Max Output 128K tokens
Modalities Text in / text out
Capabilities Agentic coding, Cost efficient, Tool calls, Reasoning
Best For Everyday coding assistance on a budget
Unit Size 1M tokens

Write a review

Note: HTML is not translated!
Bad Good
  • Stock: In Stock
  • Model: qwen3-14b-a100-1h
  • SKU: QWEN3-14B-A100-1H
Products Sold: 0
Product Views: 3
$2.50
10 or more $2.09
50 or more $1.98